Settings
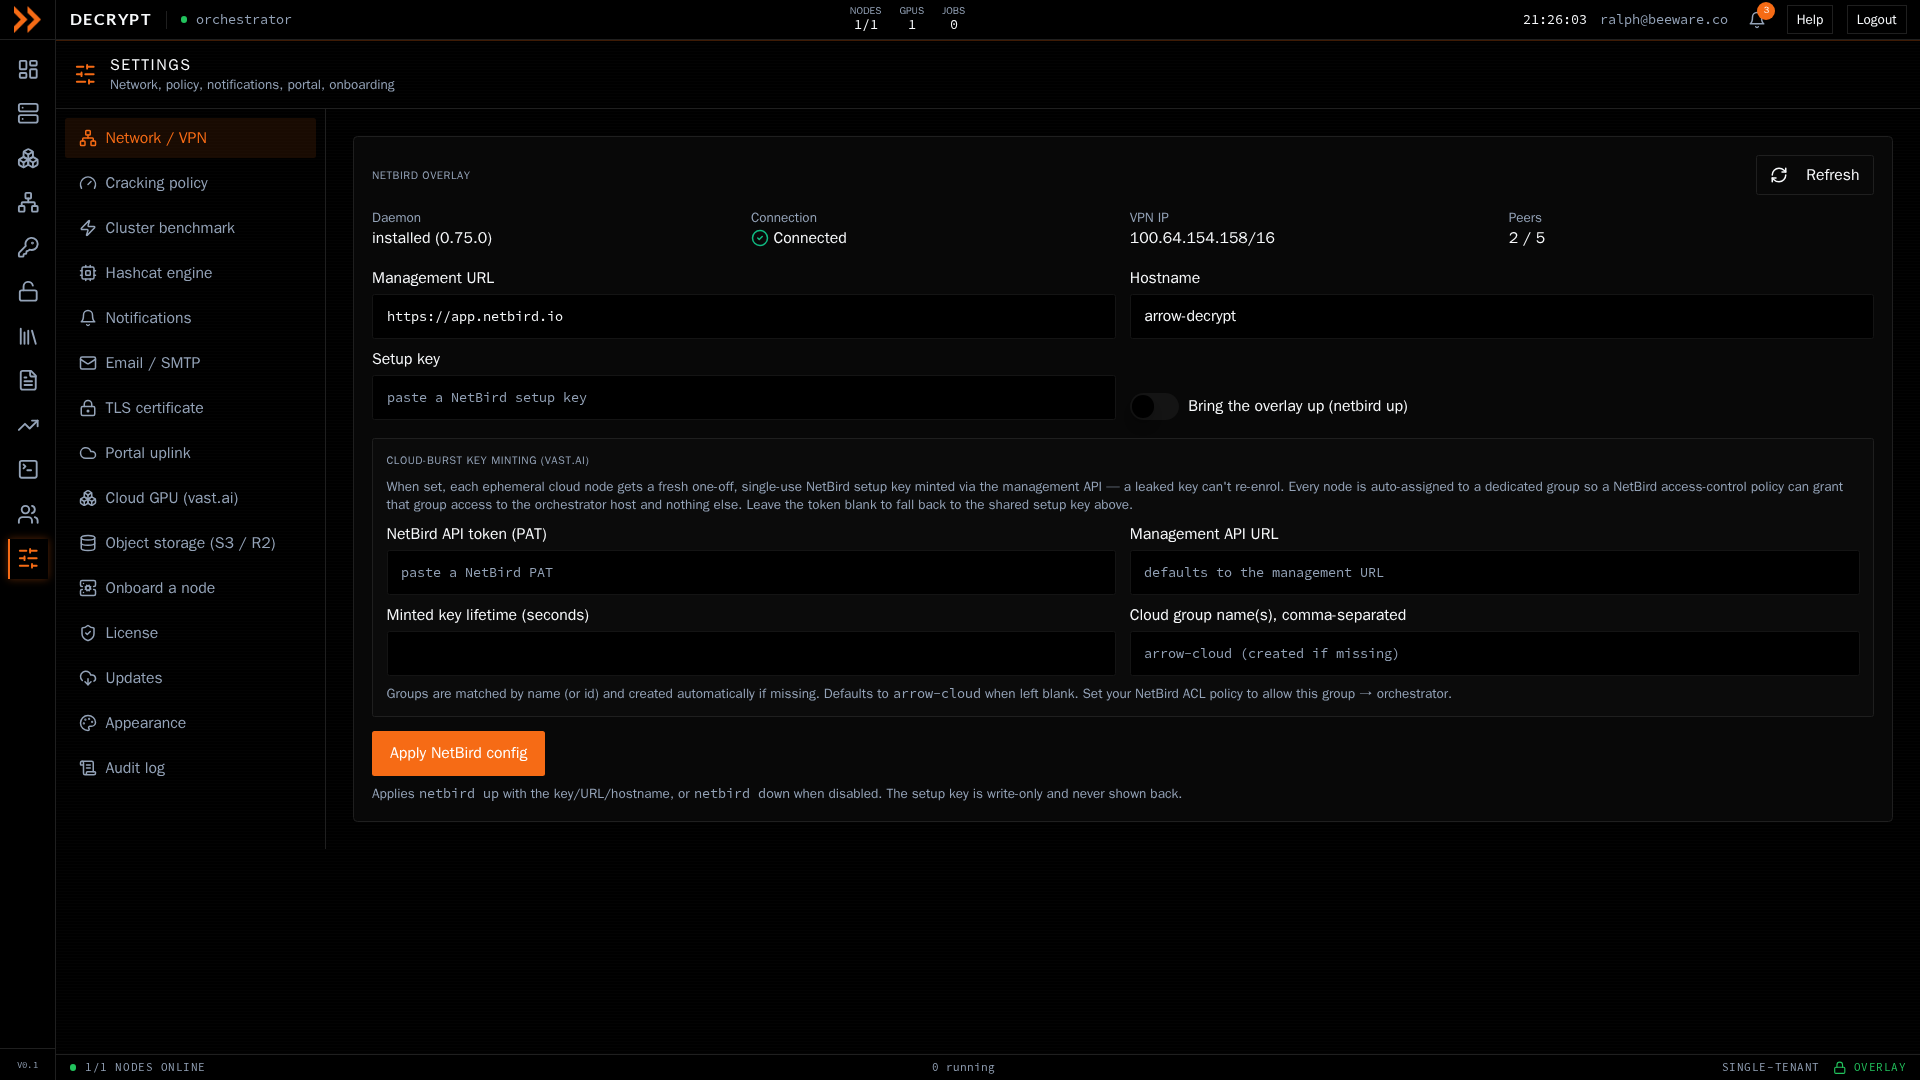
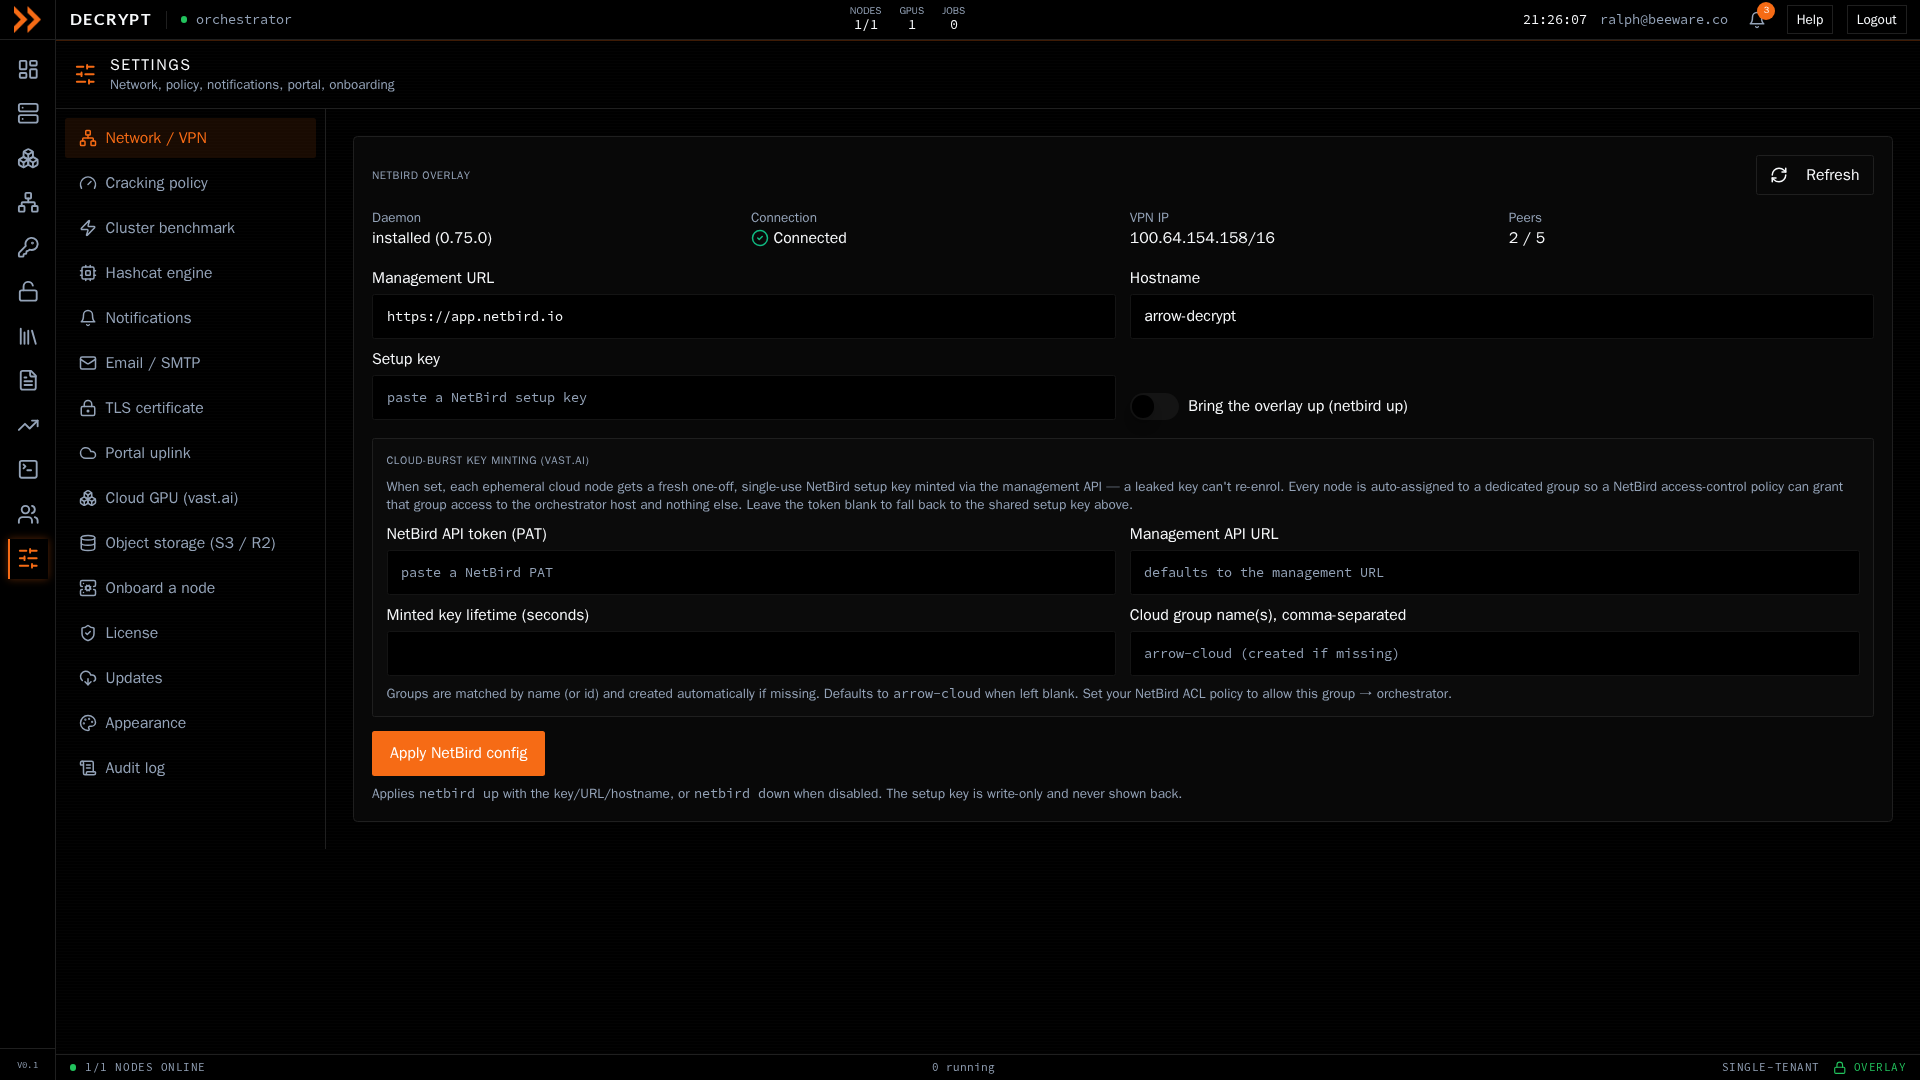
Settings is where an administrator configures the instance end to end. A rail on the left switches between sections; each one has its own Save control, so you change one area at a time.
Settings, organized into sections you configure one at a time
Settings, organized into sections you configure one at a time
The sections
Section titled “The sections”| Section | What you configure |
|---|---|
| Network / VPN | The overlay network the fleet runs on, including status and the key used to mint cloud-burst access |
| Cloud GPU | Your vast.ai connection, default rental limits, allowed regions, and a list of hosts to avoid |
| Object storage | An S3 or Cloudflare R2 bucket for wordlists, with a one-click R2 preset and a read/write test |
| Cracking policy | The gates and cost model that govern which jobs run automatically, which need confirmation, and which are rejected, plus the cloud spend cap new engagements start with |
| Cluster benchmark | Measure the fleet’s speed so job estimates are accurate, and review the benchmarks run on individual hash lists |
| Hashcat engine | The one hashcat version every rig runs, cloud GPUs included, and where each rig stands against it |
| Notifications | Webhook and Slack destinations, which events fire, and whether they go to the in-app bell or email |
| Email / SMTP | The mail server used for invitations and notifications, with a test send |
| TLS certificate | The HTTPS certificate for the console, taken from ARROW Portal or issued here with Let’s Encrypt |
| Portal uplink | An outbound status feed to ARROW Portal, and the public URL used to launch this console |
| Product telemetry | Whether anonymous performance data goes back to ARROW, exactly what it contains, and a preview of the next upload |
| Sign-in with ARROW | Whether your team can sign in with their ARROW account, and how an account nobody has added to the team is handled |
| Onboard a node | Generate the one-line command to add a rig or a vote-only witness |
| License | View license status and install or replace a license |
| Updates | See the running version, pick the stable or beta channel, install updates, and restart the service on this node |
| Appearance | The console theme; ARROW Decrypt runs in dark mode |
| Audit log | Review recent activity and export it |
Cracking policy
Section titled “Cracking policy”The policy shapes what happens when anyone queues a job. You set feasibility gates (for example, run jobs under a certain estimated length automatically, and reject ones over another), a cost and value gate (a cap on GPU-hours, a confirmation threshold, and minimum expected value), the cost model used for estimates (electricity and hardware amortization), and a default GPU-hour budget per operator over a day, week, or month. These gates are what produce the auto, confirm, and reject verdicts you see on the Jobs queue.
Under Cost model, New engagement cloud cap ($) is the cloud spend cap every new engagement starts with: the most its jobs may spend on rented cloud GPUs over the engagement’s life. Existing engagements keep their own cap, which is changed on the Cloud spend page (Spend in the sidebar). Changing the default needs the Cloud spend permission. See Crack Jobs for what happens when a job needs more than its engagement has left.
Cluster benchmark
Section titled “Cluster benchmark”Until the cluster is benchmarked, job time estimates fall back to a slow live probe and are only rough. Run Common types to benchmark the frequently used hash modes in a minute or two, or Full hashcat suite to measure every type on every rig in the background. The dashboard prompts you to benchmark when it has never been done or when your hardware has changed.
Below the cluster figures, Hash list benchmarks lists every benchmark run on a job’s own hashes, with the list, its hash mode, where it ran, its speed per GPU, how it compares with hashcat’s sample hash, and what the rental cost. A finished cloud benchmark prices every later cloud job on the same list and GPU model. You start one from a job with Benchmark this hash; see Crack Jobs.
Hashcat engine
Section titled “Hashcat engine”Every rig of this instance runs one hashcat version, and the cloud GPUs it rents install the same one. Choose it under Hashcat version for this instance. The default, Newest release, keeps the fleet on hashcat’s latest release, which matters because new hash modes arrive with new releases and a rig cannot crack a mode its version does not have. Pick an older release only when you have a reason to hold the fleet back. You are asked to confirm before the version changes; click Change version to apply it. Running shows the version in use and where it came from.
You do not have to update rigs one by one. Your rigs move onto the new version when they are idle, never during a job, and cloud GPUs rented from then on install it as they boot; GPUs already rented for a running job keep the version they started with. Rigs on different major versions never share a distributed job, so a change of major version also waits for the jobs planned on the old one.
Each rig is listed with the version it runs now and where it stands: Up to date, Moves to the new version, Installing, or Install failed, with the reason when it has not moved yet or the last try failed. To skip the wait, click Install now (or Reinstall) on a rig. A rig cannot be updated while it has a job running. Moving a rig to a new major version this way keeps it out of the jobs still planned on the old one until they finish, so you are asked to confirm first.
TLS certificate
Section titled “TLS certificate”The console is served over HTTPS with a wildcard certificate, and Certificate source decides where that certificate comes from:
- Automatic (recommended) uses the ARROW Portal certificate when this deployment is linked to ARROW Portal, and Let’s Encrypt otherwise. Leave it here unless you have a reason not to.
- ARROW Portal organization wildcard uses the certificate ARROW Portal already issues and renews for your organization. There is nothing else to fill in, because this node collects the certificate over the same uplink you set under Portal uplink.
- Let’s Encrypt (DNS-01) issues the certificate here instead. Give it a base domain, an ACME contact email, your DNS provider and that provider’s credentials. If your provider is not in the list, pick Other (manual env vars) and enter its variables yourself. Credentials are write-only and are never shown back.
Turn on Enable HTTPS, then Save TLS settings. Issue / renew now fetches a certificate immediately (the button reads Sync from Portal now when ARROW Portal is the source), and the panel above it shows the covered domains, the expiry, and the result of the last attempt. The first time you enable HTTPS the node keeps serving plain HTTP until the service is restarted; the status panel says so and puts a Restart service button next to the message, so you can finish the switch from the browser. The certificate itself lands right away and is shared with every node in the cluster.
Service control
Section titled “Service control”A few settings are only read when the service starts, enabling HTTPS being the one you are most likely to hit. Updates has a Service control block with a Restart service button that applies them, and the same button appears in the TLS certificate panel while HTTPS is saved but not yet being served.
The restart covers this node only, so a cluster is rolled one node at a time rather than taken down at once. It interrupts any jobs running on that node, and the panel and the confirmation both tell you how many first. The console is unreachable for up to a minute while the node comes back, then reloads itself. If this host does not run ARROW Decrypt as a managed service the button is disabled and the panel explains why; restart it the way the host manages its processes instead.
Product telemetry
Section titled “Product telemetry”This instance sends ARROW anonymous performance data about finished crack jobs, cloud rentals, and hash list benchmarks, so defaults, forecasts, and GPU speed tables can be tuned on real runs. It is on by default and uploads hourly, but only while the instance is linked to ARROW Portal over the Portal uplink; an unlinked instance sends nothing. The section spells out what goes and what never does:
- Sent: the hash mode, the hash count as a range, and the share of hashes cracked per step; the shape of the attack (wordlist sizes and fingerprints, stock rule names, and masks with any typed text removed); speeds, GPU models, hashcat versions, run time against the forecast, and cost; and cloud host boot times, host checks, download speeds, and country.
- Never sent: hashes, cracked passwords, or usernames; job, engagement, client, wordlist, or custom rule names; IP addresses, hostnames, user names, or emails; or anything tying the data to your organization. Records carry only a random id for this instance, shown in the section.
If you need to see exactly what leaves the instance, click Preview next upload to show the next upload as it would be sent, without sending it. Turn off Send product telemetry to stop it; nothing is sent while it is off. Send now uploads everything finished since the last upload instead of waiting for the next hourly one, and the section shows when the last upload went, what it carried, and why it failed if it did. Rotate id gives the instance a new random id once you confirm, so later uploads cannot be joined to the ones sent before.
Sign-in with ARROW
Section titled “Sign-in with ARROW”Sign-in with ARROW lets your team sign in with their ARROW account instead of a password kept here. You do not set it up on this page: it is configured in ARROW Portal, on this deployment’s page, and arrives over the Portal uplink. Until then the section reads Not configured and everyone signs in with a password. Once it is on, the section shows the Identity provider, the Callback URL, and when the configuration was last refreshed from ARROW Portal.
Proving an ARROW identity is not the same as being allowed in. Under Who may sign in with ARROW, choose how an ARROW account nobody has added to the team is handled:
- Only people already on the team refuses the account and tells the person to contact an administrator. This is the recommended setting.
- Let them request access lets an account from your organization ask to join. It appears on the Team page as Awaiting approval, with no permissions until someone approves it.
Your choice takes effect as soon as you pick it. Accounts from other organizations are always refused, and password sign-in is never turned off, so a local administrator can always get in. Roles and permissions are still set on the Team page, however people sign in.
Audit log
Section titled “Audit log”The audit log lists recent activity with the time, event, actor, source address, and details. You can export it for a SIEM in NDJSON or CEF format using the controls above the table. Viewing the audit log requires the audit permission.
Related documentation
Section titled “Related documentation”- Cloud GPUs - Uses the vast.ai and storage settings
- Wordlists - Uses the object storage settings
- GPU Nodes & Cluster - Onboard nodes and benchmark the fleet